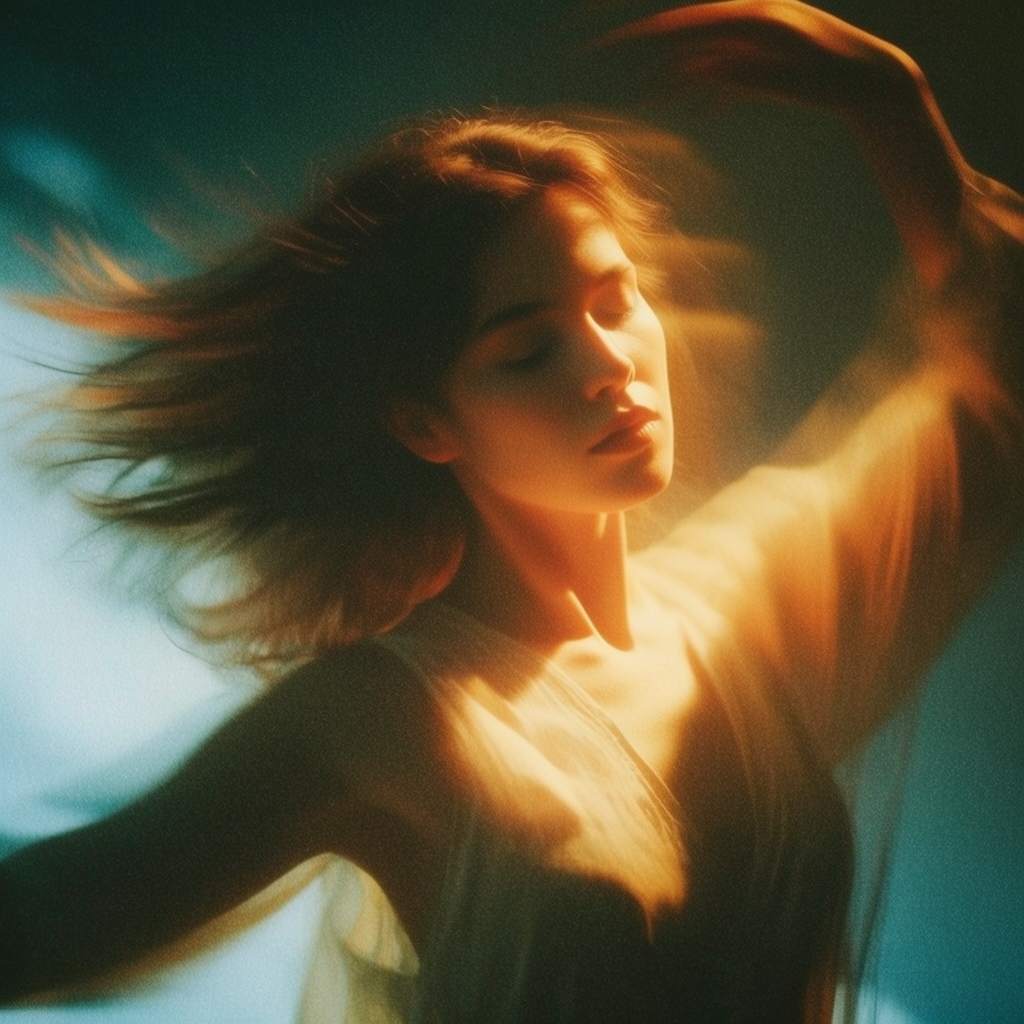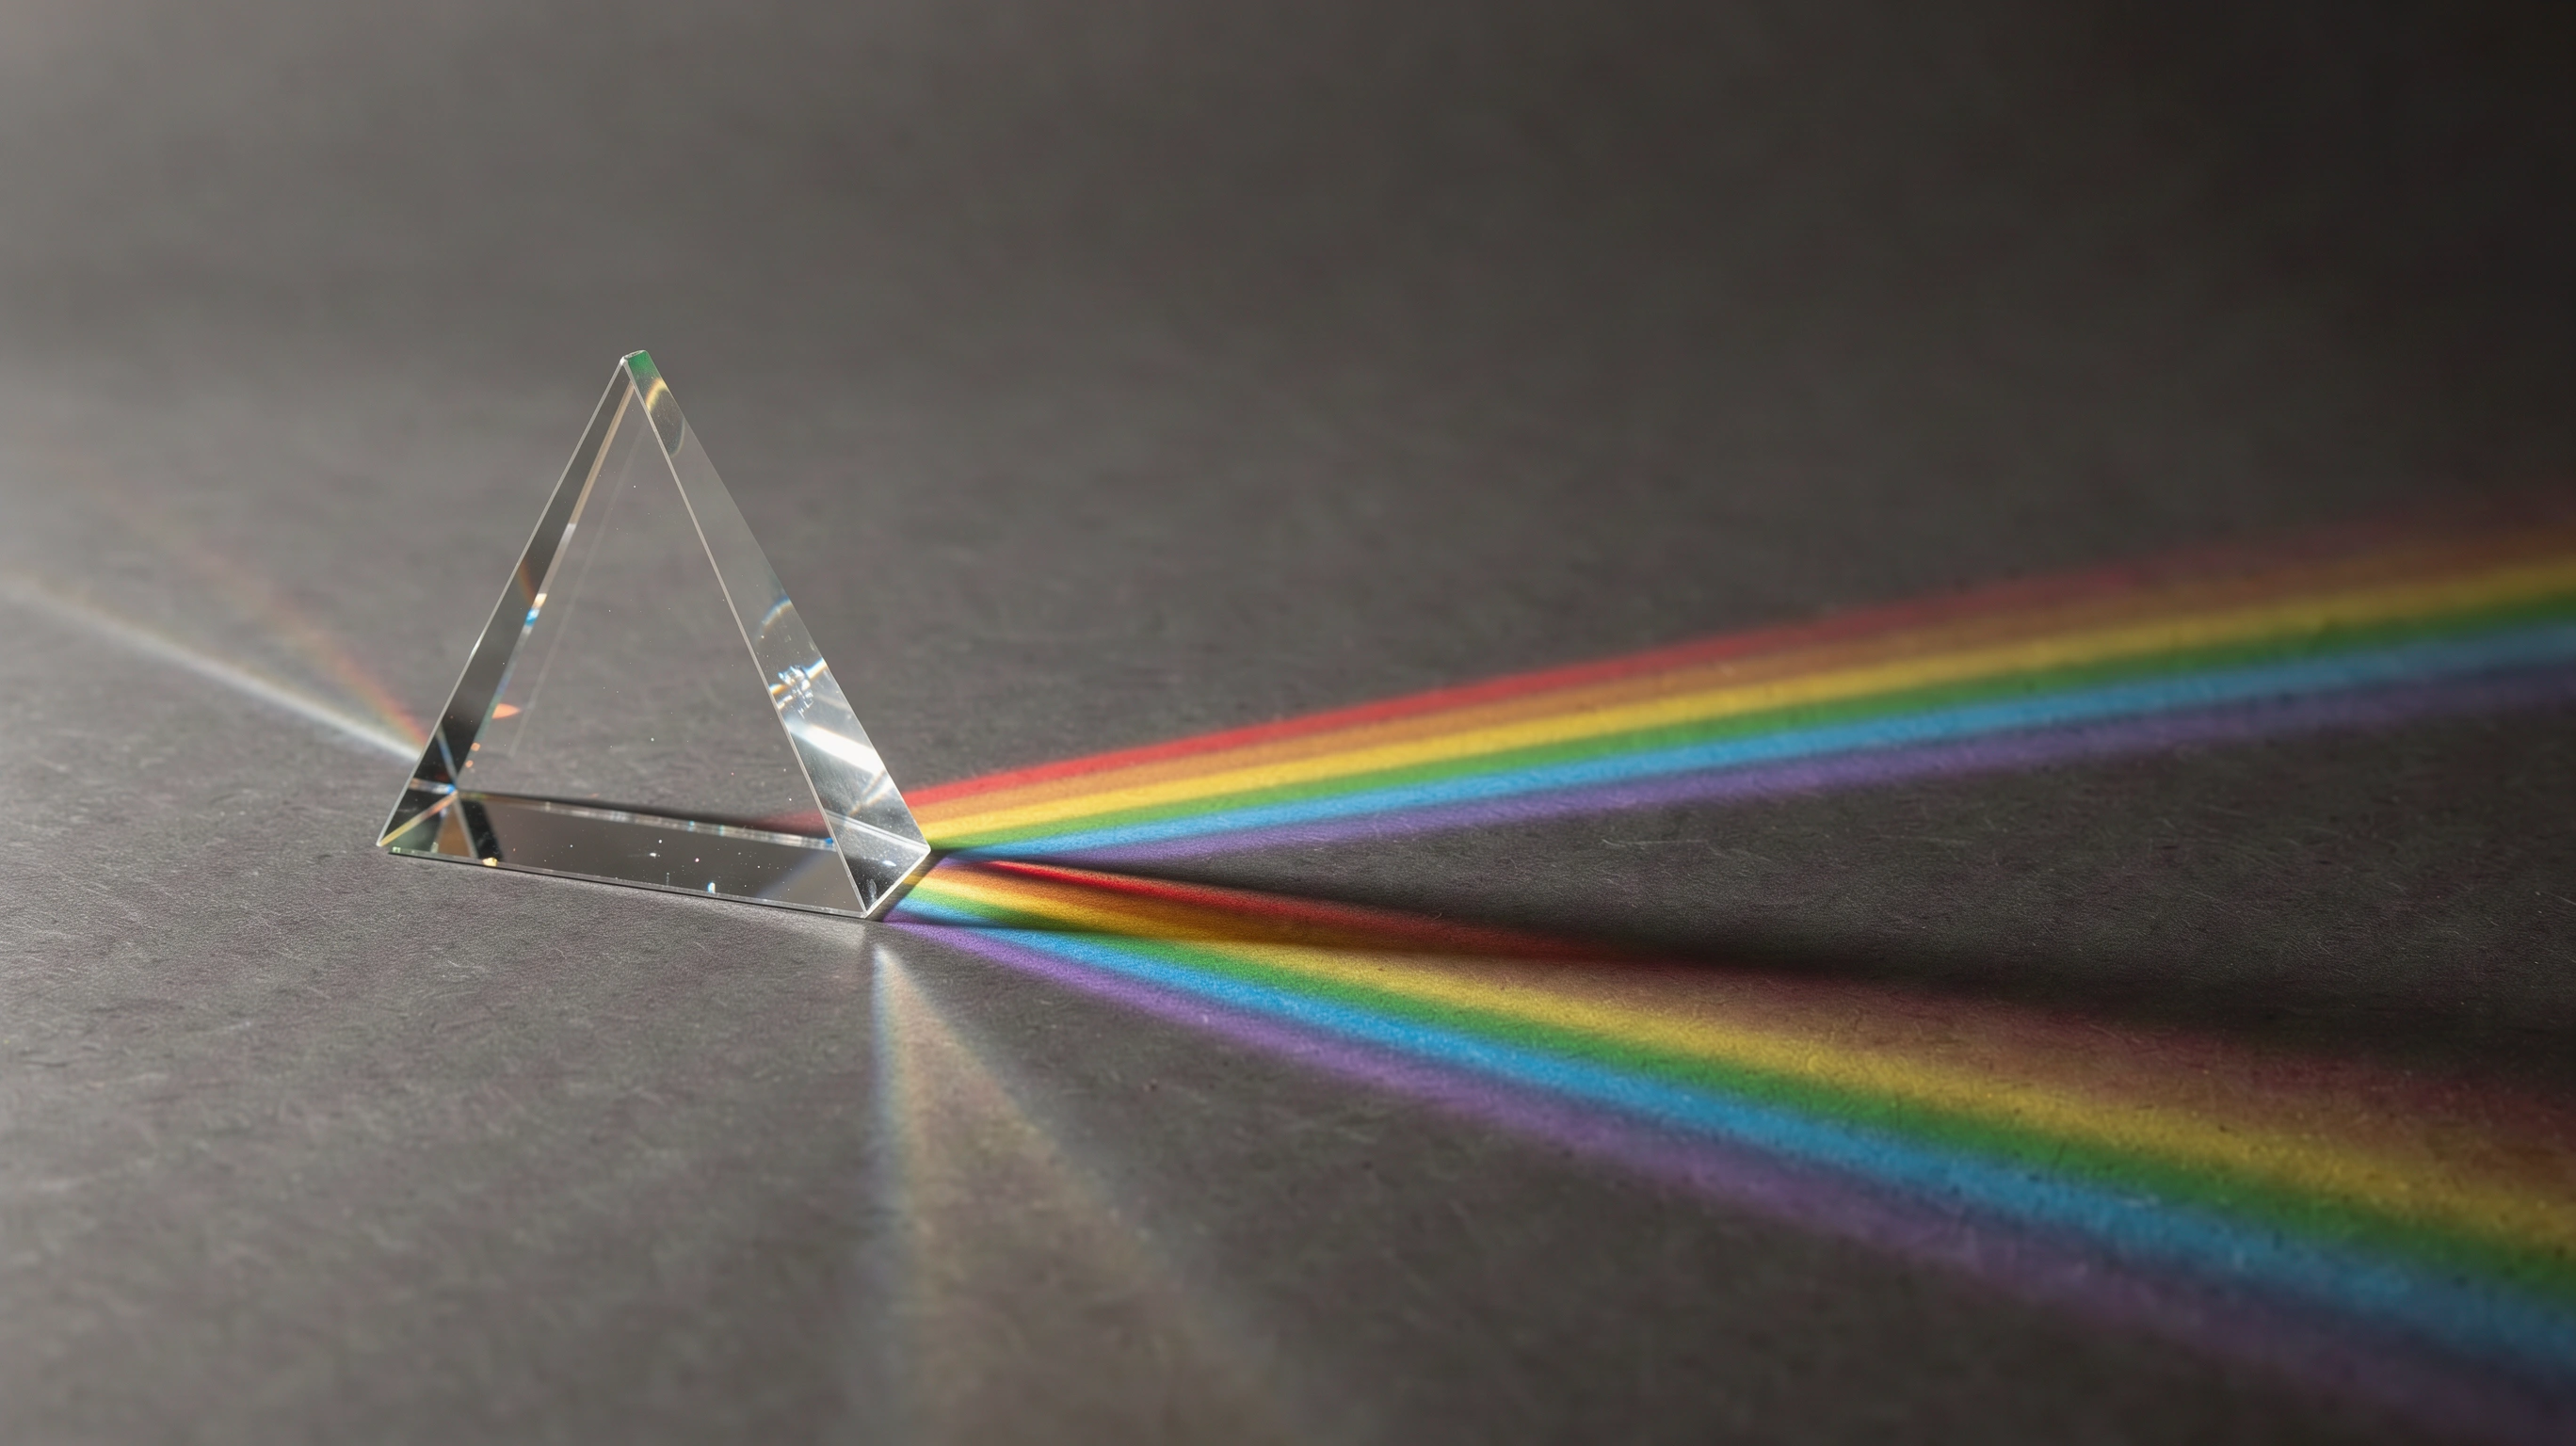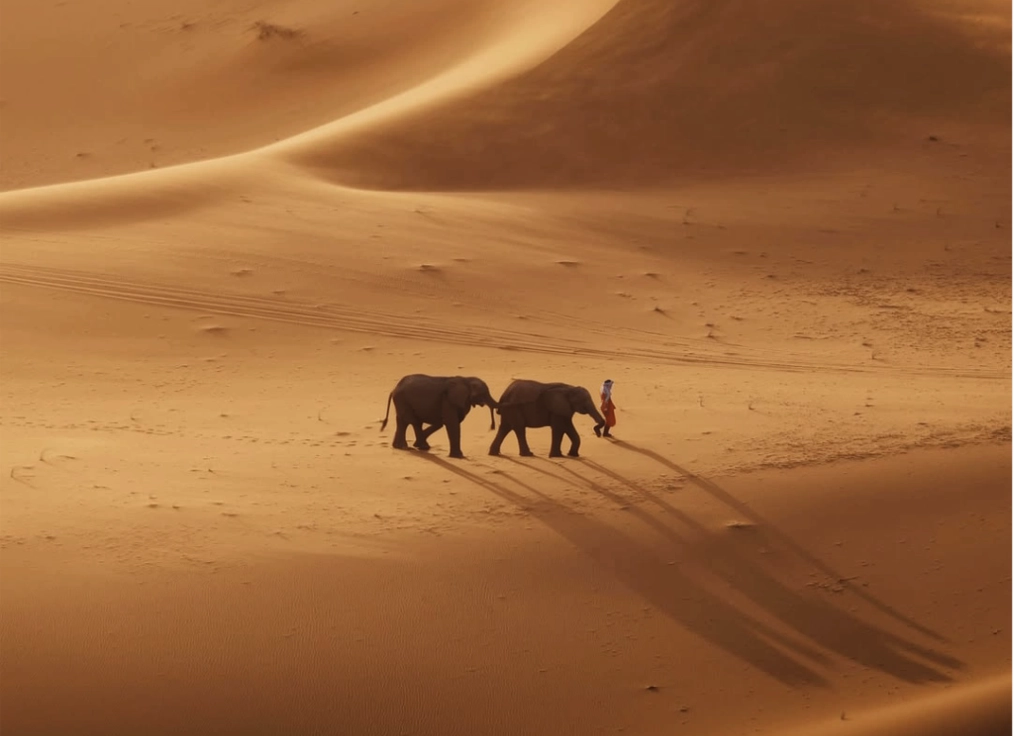
MAI-Image-2.6 is a diffusion-based generative model designed for both high-quality text-to-image synthesis and precise, controllable image-to-image editing. It progressively transforms random noise into a coherent image aligned with a given text prompt, leveraging a flow-matching loss to learn a continuous transformation between the noise distribution and the data distribution. MAI-Image-2.6 excels at precise, surgical edits with consistency - enabling users and developers to make targeted object edits, adapt layouts, update text, clean up artifacts like motion blur, and preserve visual consistency across iterations.
Quick readCRAISEE · Oct 14, 2026reference
Try it on CRAISEE nowGo create