Loading…

CRAISEE · Jun 24, 2026
OpenAI's state-of-the-art image generation model, excelling at prompt adherence, crisp text rendering, and precise editing capabilities.

CRAISEE · Jun 24, 2026
A complete guide to Seedance 2.0: ByteDance's multimodal AI video model — covering architecture, core features, and practical prompts all in one place.

CRAISEE · Jun 23, 2026
Alibaba's Happy Horse 1.1 generates videos from text, animates a single image, or builds a video from multiple reference images. Supports 720p and 1080p, 3-15 second durations, and five aspect ratios.

CRAISEE · Apr 25, 2026
Kling v3 (Video 3.0) by Kuaishou: native 4K, 60fps, multi-shot cuts, multilingual audio. Full wiki covering specs, pricing, prompts & comparisons with Runway Gen-4 and Veo 3.1.
CRAISEE · Sep 18, 2026
Pruna's highest-quality video model. Generate video from text or images with speed and quality modes, first- and last-frame control, and durations up to 15 seconds.
CRAISEE · Sep 15, 2026
Image-to-video generation with optional audio, multi-shot narrative support, and faster inference
CRAISEE · Sep 15, 2026
Generate videos from text prompts using Alibaba's Wan 3.0 Prime model. Up to 1080p and 30 seconds, with 480p, 720p, and 1080p output.
CRAISEE · Sep 15, 2026
(50% off until Aug 30!) - Wan 3.0 generates video from a text prompt or a starting image, with cinematic motion and support for 480p, 720p, and 1080p output up to 30 seconds.
CRAISEE · Sep 15, 2026
Edit videos with natural language instructions using Alibaba's Wan 2.7 VideoEdit model
CRAISEE · Sep 15, 2026
Generate videos with audio from text prompts using Alibaba's Wan 2.7 model. 1080p, up to 15 seconds, with audio synchronization.

CRAISEE · Sep 15, 2026
Generate videos from reference images or clips while preserving subject identity using Alibaba's Wan 2.7 reference-to-video model

CRAISEE · Sep 15, 2026
Generate and edit high-quality images with Alibaba's Wan 2.7 Pro with 4K output, thinking mode, text-to-image, multi-image editing, and image set generation
CRAISEE · Sep 15, 2026
Generate videos from images, with support for first-and-last-frame control, clip continuation, and audio synchronization using Alibaba's Wan 2.7 model

CRAISEE · Sep 15, 2026
Generate and edit images with Alibaba's Wan 2.7
CRAISEE · Sep 15, 2026
Alibaba Wan 2.6 text to video generation model
CRAISEE · Sep 15, 2026
Alibaba Wan 2.6 image to video generation model

CRAISEE · Sep 15, 2026
Clone voices to use with Minimax's speech-02-hd and speech-02-turbo
CRAISEE · Sep 15, 2026
Upscale and enhance video up to 4K at 60fps, with scene-aware presets for AI-generated content, short dramas, UGC, and film restoration.
CRAISEE · Sep 15, 2026
Video Upscaling from Topaz Labs
CRAISEE · Sep 15, 2026
Clean videos by automatically removing text overlays

CRAISEE · Sep 15, 2026
Google's cost-efficient video generation model with native audio, optimized for high-volume applications

CRAISEE · Sep 15, 2026
New and improved version of Veo 3 Fast, with higher-fidelity video, context-aware audio and last frame support

CRAISEE · Sep 15, 2026
New and improved version of Veo 3, with higher-fidelity video, context-aware audio, reference image and last frame support

CRAISEE · Sep 15, 2026
A faster and cheaper version of Google’s Veo 3 video model, with audio

CRAISEE · Sep 15, 2026
Sound on: Google’s flagship Veo 3 text to video model, with audio
CRAISEE · Sep 15, 2026
The most expressive Text to Speech model

CRAISEE · Sep 15, 2026
Generate multilingual text-to-speech audio in over 30 languages

CRAISEE · Sep 15, 2026
Minimax Speech 2.8 Turbo: Turn text into natural, expressive speech with voice cloning, emotion control, and support for 40+ languages
CRAISEE · Sep 15, 2026
Upscale images 2x or 4x times

CRAISEE · Sep 15, 2026
Minimax Speech 2.8 HD focuses on high-fidelity audio generation with features like studio-grade quality, flexible emotion control, multilingual support, and voice cloning capabilities

CRAISEE · Sep 15, 2026
Low‑latency MiniMax Speech 2.6 Turbo brings multilingual, emotional text-to-speech to Replicate with 300+ voices and real-time friendly pricing

CRAISEE · Sep 15, 2026
MiniMax Speech 2.6 HD delivers studio-quality multilingual text-to-audio on Replicate with nuanced prosody, subtitle export, and premium voices
CRAISEE · Sep 15, 2026
OpenAI's Most advanced synced-audio video generation
CRAISEE · Sep 15, 2026
OpenAI's Flagship video generation with synced audio
CRAISEE · Sep 15, 2026
ByteDance's flagship text-to-image and image editing model, generating sharp 1K and 2K images from text or up to 10 reference images
CRAISEE · Sep 15, 2026
Seedream 5.0 lite: image generation with built-in reasoning, example-based editing, and deep domain knowledge

CRAISEE · Sep 15, 2026
Seedream 4.5: Upgraded Bytedance image model with stronger spatial understanding and world knowledge

CRAISEE · Sep 15, 2026
Unified text-to-image generation and precise single-sentence editing at up to 4K resolution

CRAISEE · Sep 15, 2026
ByteDance's flagship multimodal video model with native audio, native 30-second generation, and large multimodal reference sets.
CRAISEE · Sep 15, 2026
A lower-cost variant of Seedance 2.0 for high-volume video generation with multimodal inputs and native audio.

CRAISEE · Sep 15, 2026
A faster variant of Seedance 2.0 for quicker video generation with multimodal inputs and native audio.

CRAISEE · Sep 15, 2026
ByteDance's multimodal video generation model with native audio, multimodal reference inputs, and intelligent duration control.

CRAISEE · Sep 15, 2026
A joint audio-video model that accurately follows complex instructions.
CRAISEE · Sep 15, 2026
Transcribe speech with ElevenLabs Scribe v2. 90+ languages, word-level timestamps, speaker diarization for up to 32 speakers, audio event tagging, and keyterm biasing. Files up to 3 GB and 10 hours.
CRAISEE · Sep 15, 2026
Top-quality agentic image model with multi-step reasoning, candidate scoring, and adjustable thinking effort
CRAISEE · Sep 15, 2026
Speed-optimized variant of Riverflow 2.5 for production and latency-sensitive workflows
CRAISEE · Sep 15, 2026
Bria AI's remove background model
CRAISEE · Sep 15, 2026
A faster, lighter Recraft image generation model at ~2048px resolution, optimized for high-volume production. Design taste and prompt accuracy at high resolution with better throughput.

CRAISEE · Sep 15, 2026
A faster, lighter Recraft image generation model optimized for high-volume and production pipelines. Same design taste as V4.1, built for speed and throughput.

CRAISEE · Sep 15, 2026
Generate production-ready SVG vector images from text prompts. Recraft V4.1's design taste applied to vector output — clean geometry, structured layers, and editable paths.

CRAISEE · Sep 15, 2026
Generate detailed SVG vector graphics from text prompts. Recraft V4.1 Pro's design taste with more geometric detail and finer paths — clean layers, editable output, and scalable to any size.

CRAISEE · Sep 15, 2026
Recraft's latest image generation model at ~2048px resolution. Same design taste and prompt accuracy as V4.1, with higher resolution for print-ready and large-scale work.

CRAISEE · Sep 15, 2026
Recraft's latest image generation model, built around design taste. Strong prompt accuracy, art-directed composition, and integrated text rendering. Fast and cost-efficient at standard resolution.

CRAISEE · Sep 15, 2026
Generate production-ready SVG vector images from text prompts. Recraft V4's design taste applied to vector output — clean geometry, structured layers, and editable paths.

CRAISEE · Sep 15, 2026
Generate detailed SVG vector graphics from text prompts. Recraft V4 Pro's design taste with more geometric detail and finer paths — clean layers, editable output, and scalable to any size.

CRAISEE · Sep 15, 2026
Recraft's latest image generation model at ~2048px resolution. Same design taste and prompt accuracy as V4, with higher resolution for print-ready and large-scale work.

CRAISEE · Sep 15, 2026
Recraft's latest image generation model, built around design taste. Strong prompt accuracy, art-directed composition, and integrated text rendering. Fast and cost-efficient at standard resolution.
CRAISEE · Sep 15, 2026
Automated background removal for images. Tuned for AI-generated content, product photos, portraits, and design workflows
CRAISEE · Sep 15, 2026
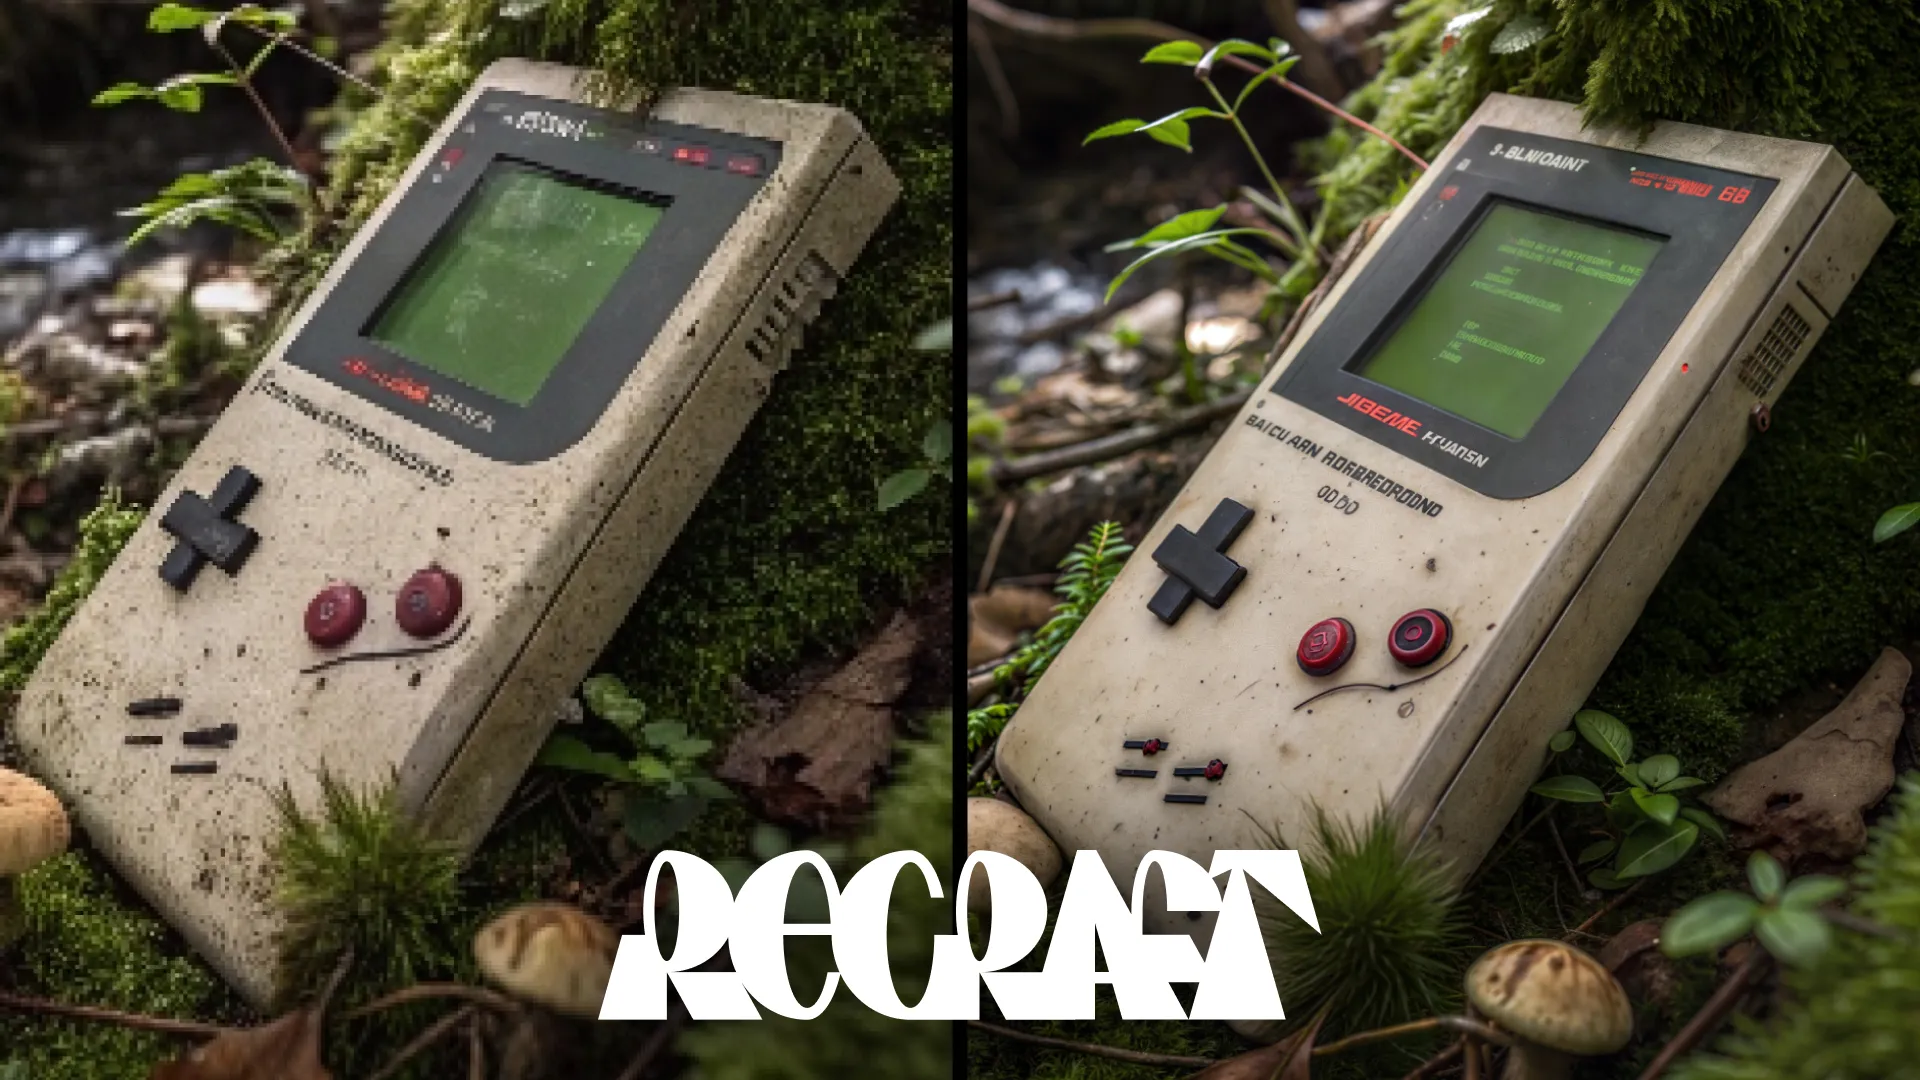
Designed to make images sharper and cleaner, Crisp Upscale increases overall quality, making visuals suitable for web use or print-ready materials.
CRAISEE · Sep 15, 2026
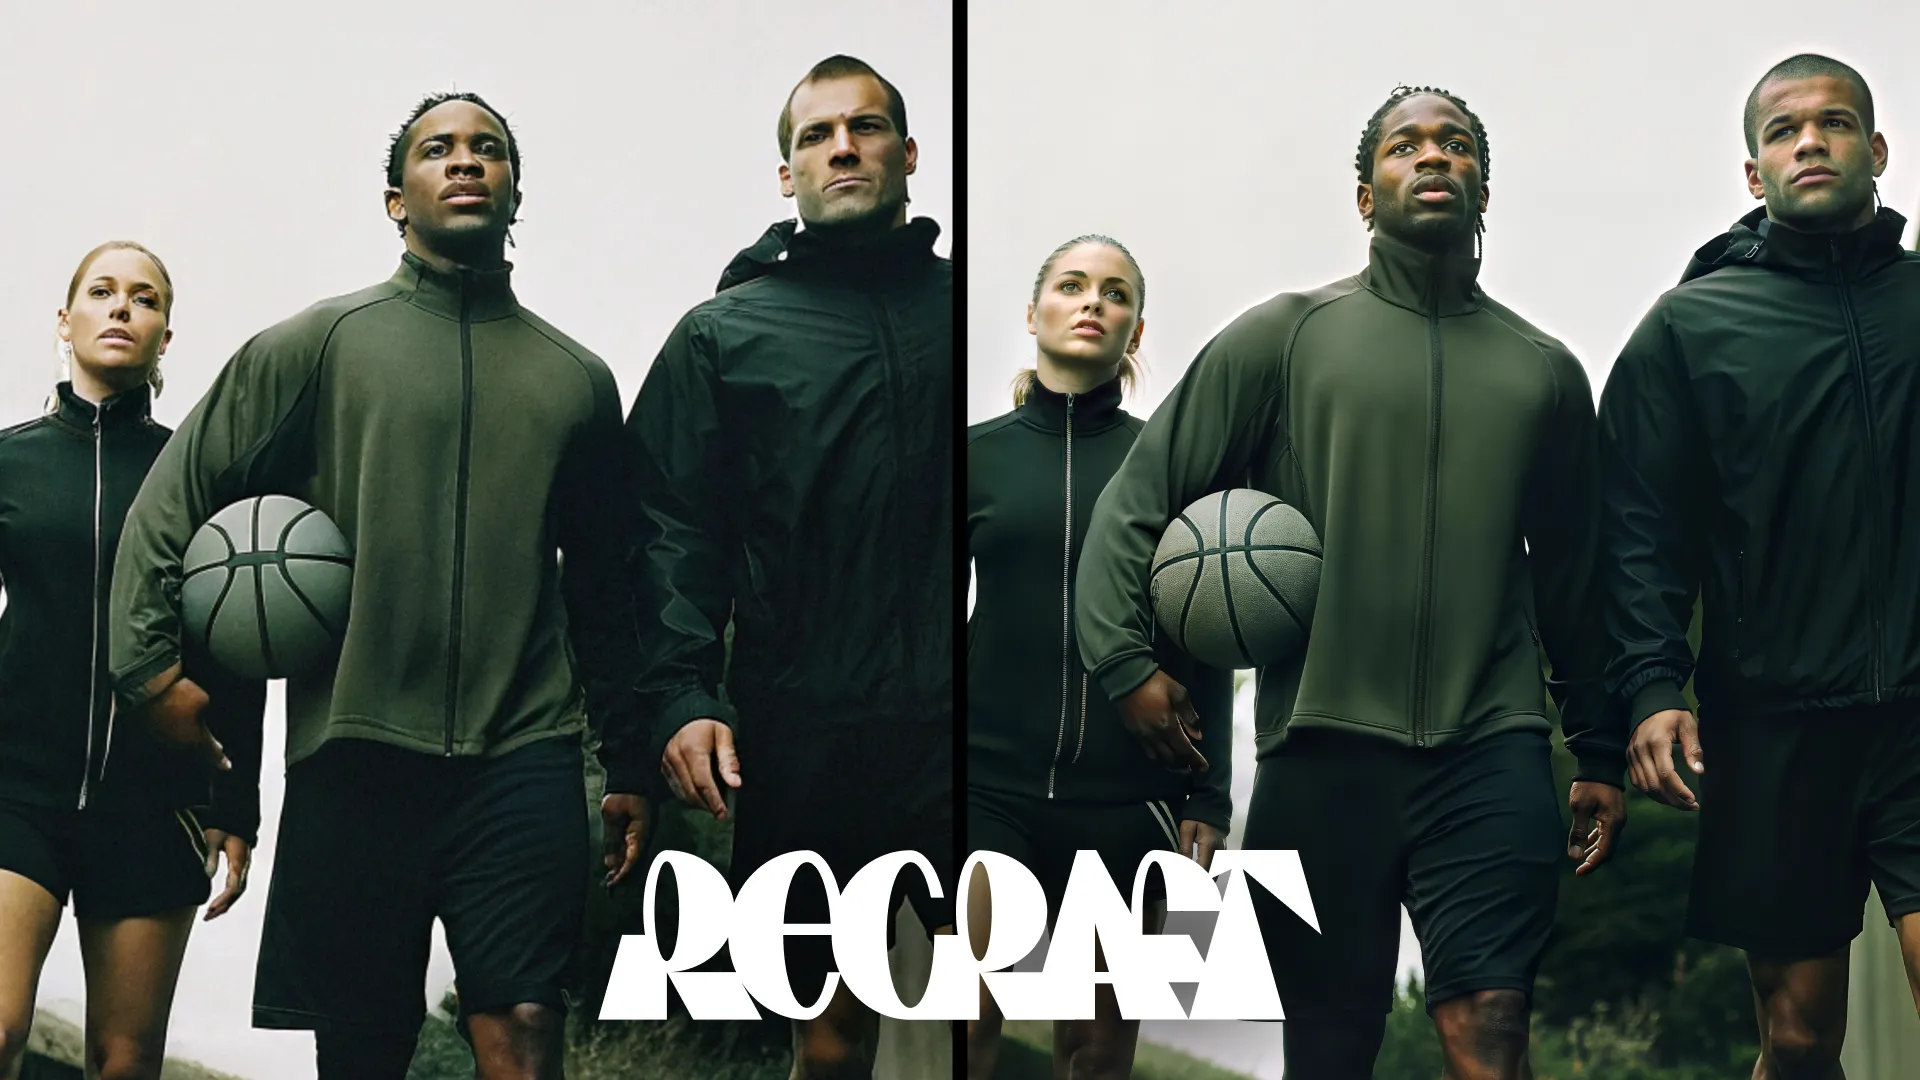
Creative Upscale focuses on enhancing details and refining complex elements in the image. It doesn’t just increase resolution but adds depth by improving textures, fine details, and facial features.

CRAISEE · Sep 15, 2026
Ultra-fast, cost-efficient realtime text-to-speech with ~120ms latency and 15-language support

CRAISEE · Sep 15, 2026
Most expressive text-to-speech model from Inworld, with natural-language steering, real-time latency, and multilingual support across 100+ languages.

CRAISEE · Sep 15, 2026
Highest-quality realtime text-to-speech with <200ms latency, emotion control, and 15-language support
CRAISEE · Sep 15, 2026
Realistic lipsync with refined human emotion capabilities
CRAISEE · Sep 15, 2026
Generate 5s and 9s 720p videos, faster and cheaper than Ray 2
CRAISEE · Sep 15, 2026
Generate 5s and 9s 540p videos, faster and cheaper than Ray 2
CRAISEE · Sep 15, 2026
Generate 5s and 9s 720p videos

CRAISEE · Sep 15, 2026
Generate 5s and 9s 540p videos

CRAISEE · Sep 15, 2026
A unified Text-to-Speech demo featuring three powerful modes: Voice, Clone and Design
CRAISEE · Sep 15, 2026
Qwen3.7-Plus is Alibaba's cost-effective multimodal model with vision-language understanding, a 1 million token context window, and strong agentic coding and tool use.
CRAISEE · Sep 15, 2026
Qwen-Image optimized by Pruna AI. Generates high fidelity 1.5MP images in 1s.
CRAISEE · Sep 15, 2026
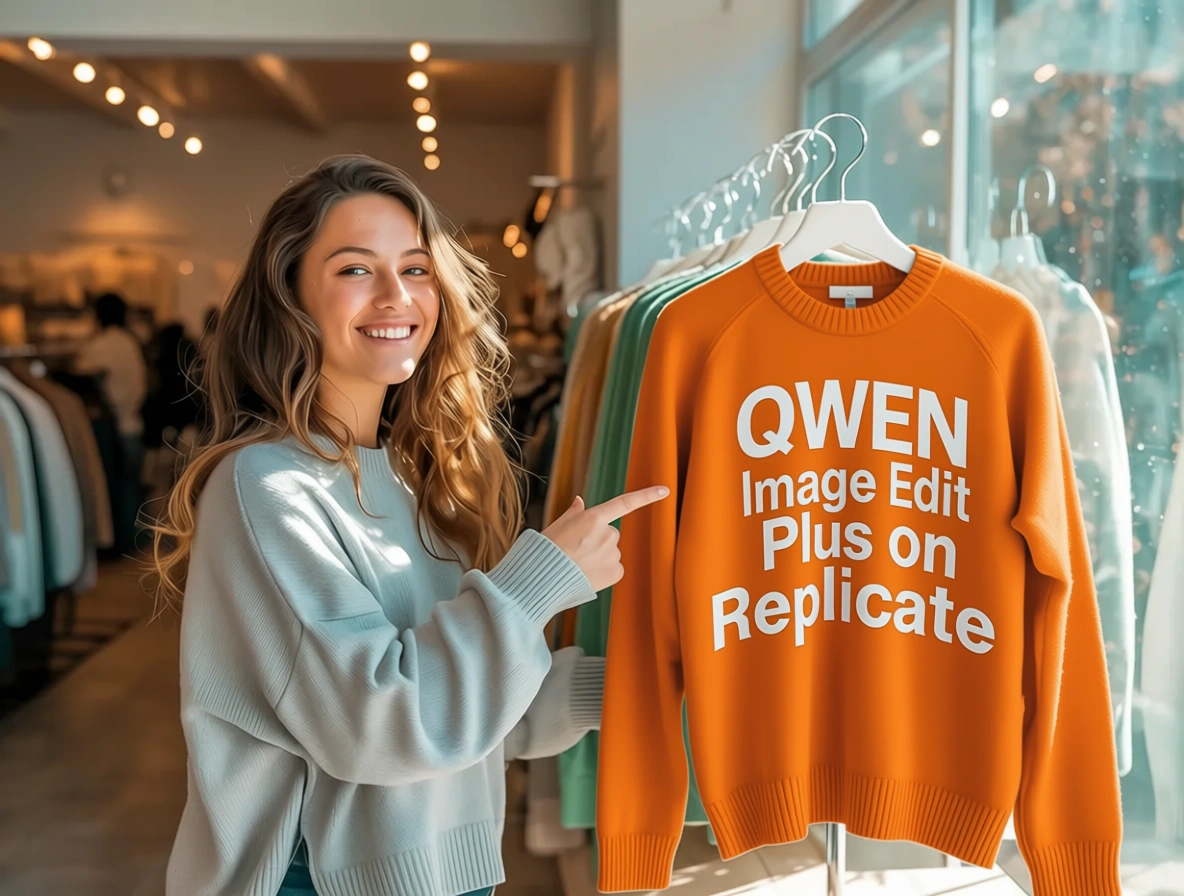
The latest Qwen-Image’s iteration with improved multi-image editing, single-image consistency, and native support for ControlNet

CRAISEE · Sep 15, 2026
400+ images in 1$ 1024 resolution// 2s /img on L40S GPU, check description and examples
CRAISEE · Sep 15, 2026
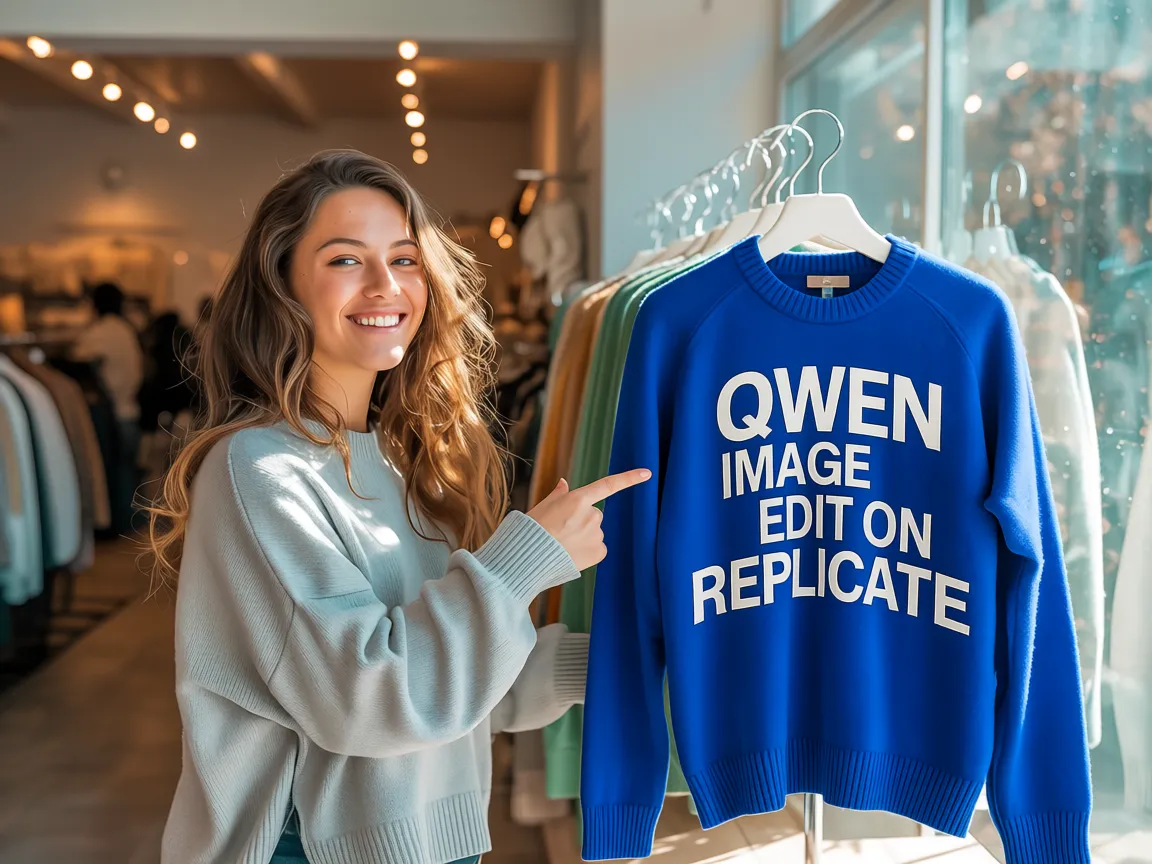
Edit images using a prompt. This model extends Qwen-Image’s unique text rendering capabilities to image editing tasks, enabling precise text editing
CRAISEE · Sep 15, 2026
Qwen-Image-3.0-Pro generates and edits images with dense, accurate text rendering, complex multi-element layouts, and photographic detail.
CRAISEE · Sep 15, 2026
Qwen-Image-3.0 generates and edits images with accurate text rendering, complex layouts, and photographic detail.

CRAISEE · Sep 15, 2026
Qwen Image 2512 is an improved version of Qwen Image with more realistic human generation, finer textures, and stronger text rendering
CRAISEE · Sep 15, 2026
The pro version of Qwen Image 2 from Alibaba's Qwen team. Enhanced text rendering, realism, and semantic adherence for high-quality image generation and editing.
CRAISEE · Sep 15, 2026
Edit videos with a text prompt and optional reference images.
CRAISEE · Sep 15, 2026
P-Video-2 is the quality-focused successor to P-Video from $0.025/s
CRAISEE · Sep 15, 2026
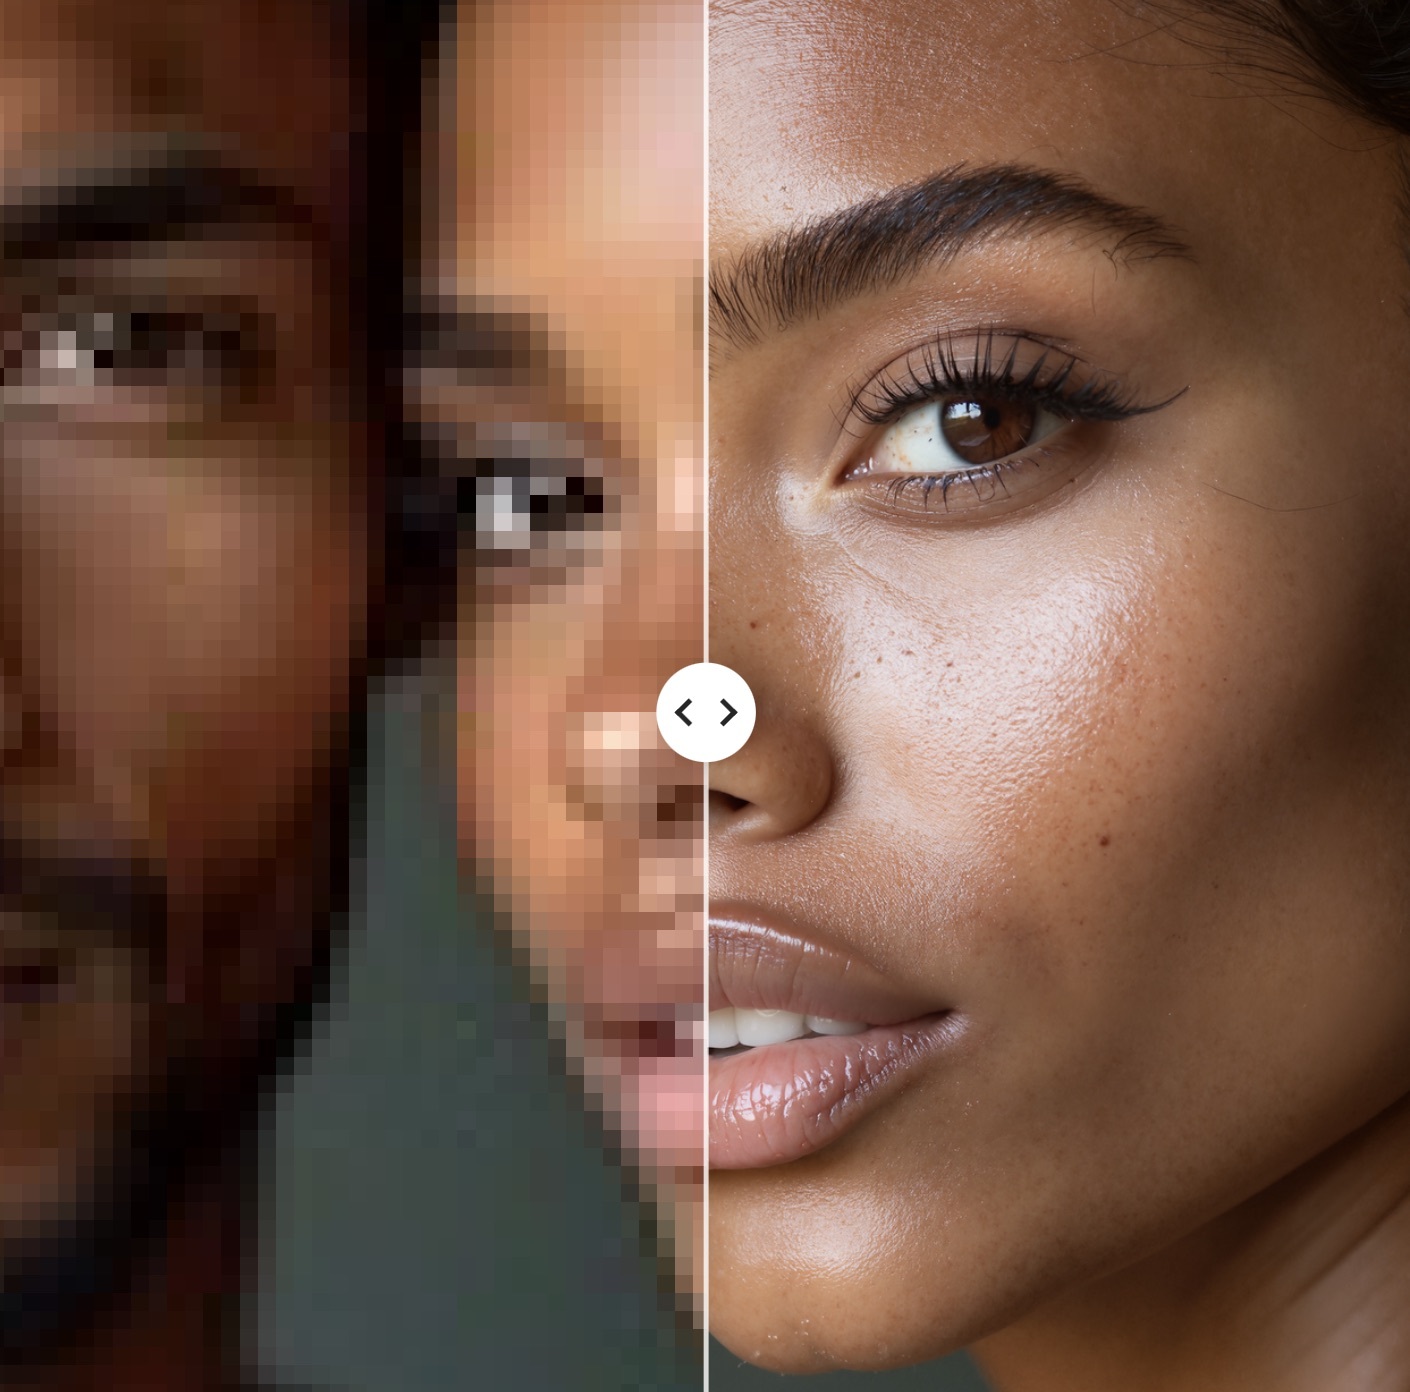
The first creative upscaler which keeps identity. Stunning photorealistic results, realistic skin, and full creative control.

CRAISEE · Sep 15, 2026
High-quality image generation and editing with support for eight reference images
CRAISEE · Sep 15, 2026
Generate high-fidelity SVG graphics from text prompts with Quiver's Arrow 1.1 Max model. Tuned for dense illustrations, detailed logos, and technical diagrams.

CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.7 Text-to-Video on CRAISEE.
CRAISEE · Sep 15, 2026
Edit one frame to update an entire video. Aleph 2.0 is Runway's in-context video editor: longer clips (up to 30s), multi-shot edits, and image-level precision via keyframe references.
CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.7 Reference-to-Video on CRAISEE.
CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.6 Text-to-Video on CRAISEE.
CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.6 Reference-to-Video Flash on CRAISEE.
CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.6 Reference-to-Video on CRAISEE.
CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.6 Image-to-Video on CRAISEE.
CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.6 Image-to-Video Flash on CRAISEE.
CRAISEE · Sep 15, 2026
Complete guide to using Wan v2.5 Text-to-Video Preview on CRAISEE.
CRAISEE · Sep 15, 2026
Veo 3 Fast is a quicker and more cost effective version of Veo 3, allowing developers to create videos with sound while maintaining high quality and optimizing for speed and business use cases. Veo 3 Fast offers both text-to-video and image-to-video modalities.
CRAISEE · Sep 15, 2026
Veo 3 is designed to handle a range of video generation tasks, from cinematic narratives to dynamic character animations. With Veo 3, you can create more immersive experiences by not only generating stunning visuals, but also audio like dialogue and sound effects.
CRAISEE · Sep 15, 2026
Seedream 4.0 is a SOTA multimodal image creation model built on leading architecture. It breaks through the boundaries of traditional text-to-image models by natively supporting text, single-image, and multi-image inputs. Users can freely combine text and images to achieve diverse creative modes within a single model—such as multi-image blending, image editing, and sequentially batch image generation, featuring subject consistency, making image creation more free and controllable.
CRAISEE · Sep 15, 2026
ByteDance's Seedance 1.5 Pro is a professional video model using V2A native generation for integrated, synced audio-visual output, enhancing efficiency of professional video creation.
CRAISEE · Sep 15, 2026
Seedance 1.0 Pro Fast delivers top performance at an unbeatable price, balancing quality, speed, and cost. Built on Seedance 1.0 Pro’s core strengths, it’s faster and more cost-efficient for creators.
CRAISEE · Sep 15, 2026
A video generation model that supports multi-shot storytelling. It excels in semantic understanding and instruction following, producing smooth, detailed, and cinematic 1080P HD videos.
CRAISEE · Sep 15, 2026
The model delivers strong photorealism, including realistic skin rendering and natural textures, while avoiding common synthetic artifacts. It produces more distinctive lighting, composition, diverse subjects, contemporary styling, and carefully considered scene elements. For illustration, it generates original characters and forms with sophisticated and unexpected color combinations.
CRAISEE · Sep 15, 2026
The model delivers strong photorealism, including realistic skin rendering and natural textures, while avoiding common synthetic artifacts. It produces more distinctive lighting, composition, diverse subjects, contemporary styling, and carefully considered scene elements. For illustration, it generates original characters and forms with sophisticated and unexpected color combinations.

CRAISEE · Sep 15, 2026
GPT Image 2.5 Flare generates images from text and image inputs, optimized for fast, high-quality everyday image generation.

CRAISEE · Sep 15, 2026
GPT Image 2.5 Sunburst generates and edits images from text and image inputs, with a focus on precise editing.
CRAISEE · Sep 15, 2026
Recraft V2 is an image generation model released in March 2024 and the first model trained from scratch by Recraft. With 20 billion parameters, it was a breakthrough in human anatomical accuracy and the first to support brand consistency and brand color inputs. It also introduced vector image generation (SVG output), as well as minimalistic icon and illustration styles.
CRAISEE · Sep 4, 2026
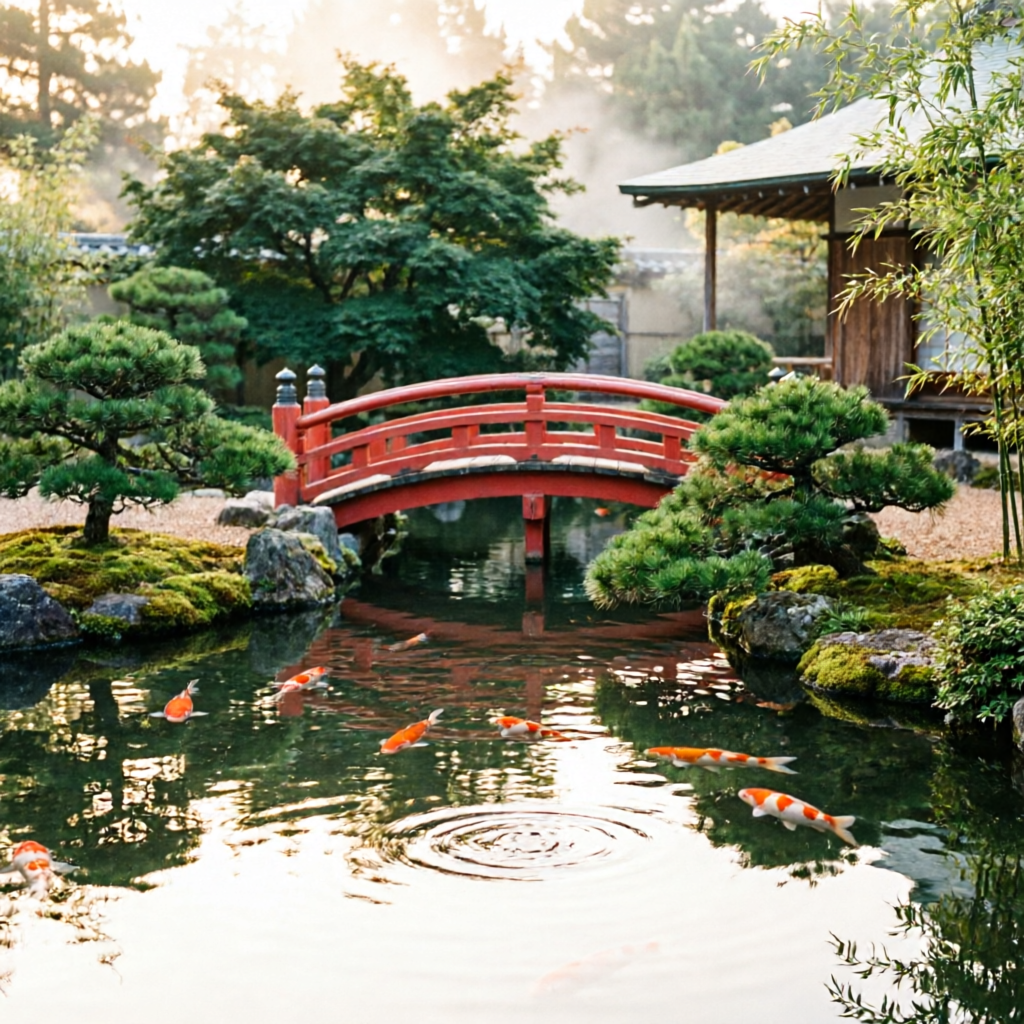
Camera-aware edits for Qwen/Qwen-Image-Edit-2509 with Lightning + multi-angle LoRA
CRAISEE · Sep 4, 2026
A next-generation image generation and editing model from Alibaba's Qwen team. Supports text-to-image and image editing with strong text rendering, especially for Chinese.
CRAISEE · Sep 4, 2026
Fast video generation with text-to-video, image-to-video, and start-end-to-video modes. Up to 16 seconds at 1080p with synchronized audio.
CRAISEE · Sep 4, 2026
PixVerse's flagship video generation model. Generate cinematic videos with synchronized audio, multi-shot sequences, and precise camera control.
CRAISEE · Sep 4, 2026
High-fidelity video generation with text-to-video, image-to-video, and start-end-to-video modes. Up to 16 seconds at 1080p with synchronized audio.

CRAISEE · Sep 4, 2026
Latest video model from Pixverse with astonishing physics
CRAISEE · Sep 4, 2026
p-video-animate animates a reference image with the motion and audio of a source video. Optimized for speed and cost — 5.24s per 1s of video.
CRAISEE · Sep 4, 2026
p-video-replace swaps the person in a video with one from a reference image, keeping motion, timing, camera, and scene exactly as they were. 3.58s per 1s of video generated.
CRAISEE · Sep 4, 2026
p-video-avatar is the fastest and cheapest avatar/lipsync video model on the market.

CRAISEE · Sep 4, 2026
Fast video generation with built-in draft mode for rapid creative iteration. Text-to-video, image-to-video, and audio-to-video in a single endpoint.

CRAISEE · Sep 4, 2026
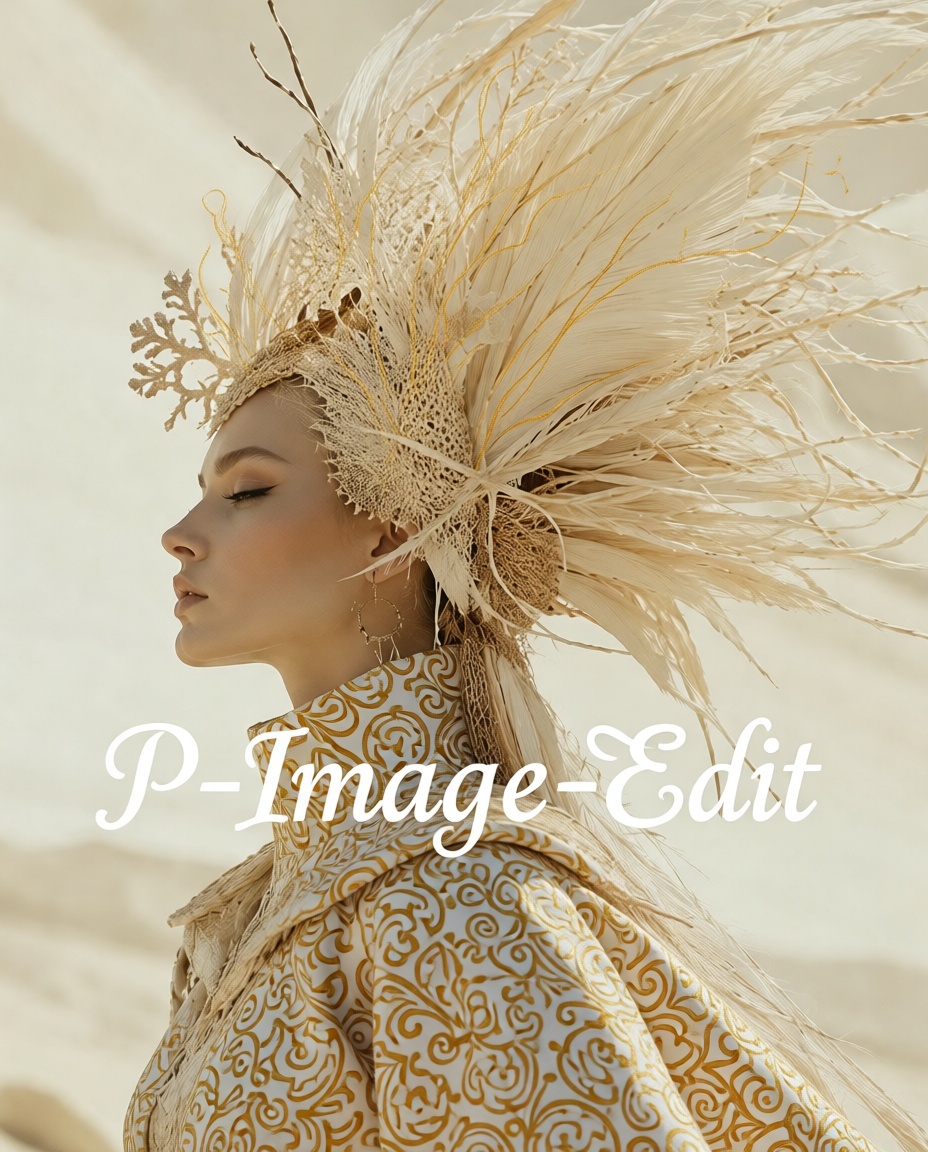
P-Image-Ideogram is Pruna AI’s text-to-image model starting from 0,003$ per generation.
CRAISEE · Sep 4, 2026
A sub 1 second 0.01$ multi-image editing model built for production use cases. For image generation, check out p-image here: https://replicate.com/prunaai/p-image

CRAISEE · Sep 4, 2026
A sub 1 second text-to-image model built for production use cases.
CRAISEE · Sep 4, 2026
A film-grade digital human model that generates realistic video from a single image, audio clip, and optional text prompt.
CRAISEE · Sep 4, 2026
Ovi: generate videos with audio from image and text inputs
CRAISEE · Sep 4, 2026
OpenAI's fast, lightweight reasoning model
CRAISEE · Sep 4, 2026
A small model alternative to o1
CRAISEE · Sep 4, 2026
Advanced reasoning model

CRAISEE · Sep 4, 2026
Google's state of the art image generation and editing model 🍌🍌

CRAISEE · Sep 4, 2026
Google's latest image editing model in Gemini 2.5
CRAISEE · Sep 4, 2026
OpenAI's first o-series reasoning model

CRAISEE · Sep 4, 2026
Reimagine any song in a different style — change voice, instruments, genre, and arrangement while keeping the original melody

CRAISEE · Sep 4, 2026
Generate full-length songs with vocals, lyrics, and rich instrumentation from a text prompt

CRAISEE · Sep 4, 2026
Generate full-length songs or instrumentals from a text prompt, with optional auto-generated lyrics
CRAISEE · Sep 4, 2026
Compose a song from a prompt or a composition plan
CRAISEE · Sep 4, 2026
FLUX Kontext max with list input for multiple images

CRAISEE · Sep 4, 2026
Create 5s 480p videos from a text prompt

CRAISEE · Sep 4, 2026
Generate 30-second music clips from text prompts or images with Lyria 3, Google's music generation model
CRAISEE · Sep 4, 2026
Modify a video with style transfer and prompt-based editing

CRAISEE · Sep 4, 2026
Generate full-length songs up to 3 minutes from text prompts or images with Lyria 3 Pro, Google's most capable music generation model

CRAISEE · Sep 4, 2026
Fast video generation with text-to-video and image-to-video, portrait and landscape support, synchronized audio, and frame interpolation. Up to 20 seconds at 1080p, and 4K resolution.

CRAISEE · Sep 4, 2026
Lyria 2 is a music generation model that produces 48kHz stereo audio through text-based prompts
CRAISEE · Sep 4, 2026
Edit and transform videos with text prompts and reference images. Style transfers, object replacement, character transformation, and more.

CRAISEE · Sep 4, 2026
High-fidelity video generation with portrait support, audio-to-video, retake, and extend. Text, image, and audio-driven creation up to 4K at 50 FPS.

CRAISEE · Sep 4, 2026
Lightning-fast video generation with portrait support, camera controls, and synchronized audio. Up to 20 seconds at 1080p, 4K at 50 FPS.
CRAISEE · Sep 4, 2026
A 17 billion parameter model with 128 experts
CRAISEE · Sep 4, 2026
Studio-grade lipsync in minutes, not weeks

CRAISEE · Sep 4, 2026
Fast lip-sync: replace or dub audio on any video with quick audio-driven lip sync
CRAISEE · Sep 4, 2026
High-accuracy lip-sync: replace or dub audio on any video with avatar-inference lip sync
CRAISEE · Sep 4, 2026
Generate realistic lipsyncs with Sync Labs' 2.0 model

CRAISEE · Sep 4, 2026
Foundation image model from Krea, tuned for expressive illustration, anime, and painterly styles. Fast and consistent across artistic directions.
CRAISEE · Sep 4, 2026
Generate realistic lipsync animations from audio for high-quality synchronization

CRAISEE · Sep 4, 2026
Kling Video 3.0: Generate cinematic videos up to 15 seconds with multi-shot control, native audio, and improved consistency

CRAISEE · Sep 4, 2026
Kling Video 3.0 Omni: Unified multimodal video generation with reference images, video editing, native audio, and multi-shot control

CRAISEE · Sep 4, 2026
Krea's flagship foundation image model. Larger and more flexible than Krea 2 Medium, with particular strength in photorealism and expressive artistic styles.

CRAISEE · Sep 4, 2026
Kling 2.6 Pro: Top-tier image-to-video with cinematic visuals, fluid motion, and native audio generation

CRAISEE · Sep 4, 2026
Kling 3.0 motion control: transfer motion from a reference video to any character image with improved consistency and quality.
CRAISEE · Sep 4, 2026
Modify an existing video through natural-language commands, changing subjects, environments, and visual style while preserving the original motion and timing.

CRAISEE · Sep 4, 2026
Moonshot AI's frontier open model, built for long-horizon coding, agent swarms, and autonomous software engineering. 1 trillion parameters, 262k context window, vision and tool use.

CRAISEE · Sep 4, 2026
Create avatar videos with realistic humans, animals, cartoons, or stylized characters
CRAISEE · Sep 4, 2026
Add lip-sync to any video with an audio file or text
CRAISEE · Sep 4, 2026
Kimi K2 Thinking is the latest, most capable version of an open-source thinking model.

CRAISEE · Sep 4, 2026
Moonshot AI's latest open model. It unifies vision and text, thinking and non-thinking modes, and single-agent and multi-agent execution into one model

CRAISEE · Sep 4, 2026
Use this ultra version of Imagen 4 when quality matters more than speed and cost

CRAISEE · Sep 4, 2026
Use this fast version of Imagen 4 when speed and cost are more important than quality
CRAISEE · Sep 4, 2026
Professional-grade image upscaling, from Topaz Labs
CRAISEE · Sep 4, 2026
Google's Imagen 4 flagship model

CRAISEE · Sep 4, 2026
The highest quality Ideogram v4 model. v4 creates images with stunning realism, creative designs, and consistent styles

CRAISEE · Sep 4, 2026
Balance speed, quality and cost. Ideogram v4 creates images with stunning realism, creative designs, and consistent styles

CRAISEE · Sep 4, 2026
Alibaba's Happy Horse 1.0 generates videos from text prompts or animates a single image into video. Supports 720p and 1080p, 3-15 second durations, and five aspect ratios.

CRAISEE · Sep 4, 2026
Convert text to natural-sounding speech with xAI's Grok TTS. 5 voices, 20 languages, expressive speech tags, and high-fidelity MP3 / WAV / telephony audio output.
CRAISEE · Sep 4, 2026
Transcribe audio to text with xAI's Grok. Handles 25 languages, word-level timestamps, speaker diarization, multichannel audio, and files up to 500 MB.
CRAISEE · Sep 4, 2026
Image-to-video with synchronized audio using xAI's Grok Imagine Video 1.5 preview model
CRAISEE · Sep 4, 2026
Granite Vision 4.1 4B is a vision-language model (VLM) that delivers frontier-level performance on structured document extraction tasks — chart extraction, table extraction, and semantic key-value pair extraction — in a compact 4B parameter footprint
CRAISEE · Sep 4, 2026
xAI's higher-quality image model with sharper details, better text rendering, and 2k output

CRAISEE · Sep 4, 2026
xAI's Grok Imagine Image 2.0 — text-to-image generation and editing with a quality control and output up to 2k
CRAISEE · Sep 4, 2026
Granite Speech 4.1 2B is a compact and efficient speech-language model, specifically designed for multilingual automatic speech recognition (ASR) and bidirectional automatic speech translation (AST) for English, French, German, Spanish, Portuguese and Jap
CRAISEE · Sep 4, 2026
Granite-embedding-small-english-r2 is a 47M parameter dense biencoder embedding model from the Granite Embeddings collection that can be used to generate high quality text embeddings.
CRAISEE · Sep 4, 2026
Granite-4.2-8B is the mid-size reasoning model in the Granite 4.2 family. It delivers strong performance on reasoning-intensive tasks by leveraging built-in <think>...</think> chain-of-thought.
CRAISEE · Sep 4, 2026
Granite-4.1-8B is a 8B parameter long-context instruct model finetuned from Granite-4.1-8B-Base using a combination of open source instruction datasets with permissive license and internally collected synthetic datasets.
CRAISEE · Sep 4, 2026
OpenAI's GPT-5.6 balanced tier, tuned for everyday production work at roughly half the cost of the flagship.
CRAISEE · Sep 4, 2026
OpenAI's GPT-5.6 flagship tier, built for complex professional work, coding, and deep multi-step reasoning.
CRAISEE · Sep 4, 2026
OpenAI's GPT-5.6 cost-optimized tier, built for fast, high-volume, latency-sensitive workloads.
CRAISEE · Sep 4, 2026
Google's fast multimodal model with frontier reasoning across agents, coding, and long-context tasks
CRAISEE · Sep 4, 2026
Google's fast multimodal video generation and editing model with native audio, using the Interactions API
CRAISEE · Sep 4, 2026
Upscale videos to higher resolution with FLUX super-resolution. Precise mode sharpens and stays faithful to the source; creative mode restores and invents fine detail.

CRAISEE · Sep 4, 2026
Translate audio and video into 90+ languages while preserving each speaker's voice, emotion, and timing
CRAISEE · Sep 4, 2026
Rig any 3D bipedal character mesh
CRAISEE · Sep 4, 2026
Anthropic's most agentic Sonnet model, bringing frontier-level coding and tool use at Sonnet's speed and price
CRAISEE · Sep 4, 2026
Claude Fable 5 from Anthropic: the next generation of intelligence for the hardest knowledge work and coding problems.
CRAISEE · Sep 4, 2026
Remove backgrounds from images.
CRAISEE · Sep 4, 2026
Wan 3.0 Video Prime is Alibaba’s high-speed, all-in-one AI video generation model for creating polished clips from text, images, video, and audio references. It produces videos up to 30 seconds long with synchronized dialogue, music, and sound effects, while accelerated generation makes it ideal for rapid creative iteration and production workflows.
CRAISEE · Sep 4, 2026
Convert raster images (PNG, JPEG, WebP) into clean SVGs with Quiver's Arrow 1.1 vectorization model. Great for turning logos and icons into editable vectors.
CRAISEE · Sep 4, 2026
Convert complex raster images into high-fidelity SVGs with Quiver's Arrow 1.1 Max vectorization model. Tuned for detailed images where fine structure and alignment matter.
CRAISEE · Sep 4, 2026
Veo 3.1 Fast is a specialized, high-speed variant of Google DeepMind’s Veo 3.1 text-to-video model, optimized for rapid generation of 8-second, high-fidelity videos. It is designed to create cinematic, 1080p, or 720p content with improved prompt adherence and native audio, making it ideal for creating quick, high-quality video clips, social media content, and ad creatives.
CRAISEE · Sep 4, 2026
All-in-one video generation model supporting text-to-video, image-to-video, first/last-frame, and omni-modal reference-based generation (image, video, and audio references) with synchronized audio, at up to 30 seconds per clip.
CRAISEE · Sep 4, 2026
Veo 3.1 Lite Preview is a high-efficiency, developer-first video model providing high-fidelity video generation, editing, and cinematic control. It leverages the state-of-the-art Veo 3.1 model to democratize professional-grade video AI by offering a scalable, programmable interface for creators and enterprises.
CRAISEE · Sep 4, 2026
Veo 3.1 is Google's state-of-the-art model for generating high-fidelity, 8-second 720p, 1080p or 4k videos featuring stunning realism and natively generated audio.
CRAISEE · Sep 4, 2026
ByteDance-Seedream-5.0-lite is the latest image generation model released by BytePlus. For the first time, it introduces web-connected retrieval, enabling the model to fuse real-time online information to significantly improve the timeliness and relevance of generated images. The model’s reasoning and comprehension capabilities are further upgraded, allowing it to accurately interpret complex prompts and visual inputs. In addition, ByteDance-Seedream-5.0-lite delivers notable improvements in global knowledge coverage, reference consistency, and professional-grade scene generation, making it well suited for enterprise-level visual creation workflows.
CRAISEE · Sep 4, 2026
Seedream-5.0-Pro, ByteDance's newest image generation model, delivers comprehensive upgrades for complex, lifelike image creation and editing, ushering in a new phase of controllable visual production. It stands out with precise editing control, robust commercial applicability and natural rendering results.
CRAISEE · Sep 4, 2026
V4.1 is built on the same visual aesthetic and the same eye for what looks right, just pushed further across every dimension. The photorealism is more natural. The gradients are dreamier. Illustration styles are now possible that simply weren't before. And this is a model that reads a short prompts easier and creates something worth stopping for. V4.1 Utility is designed for when restraint is the aesthetic choice, with flat lighting, front-facing composition, and simple, controlled scenes.
CRAISEE · Sep 4, 2026
V4.1 is built on the same visual aesthetic and the same eye for what looks right, just pushed further across every dimension. The photorealism is more natural. The gradients are dreamier. Illustration styles are now possible that simply weren't before. And this is a model that reads a short prompts easier and creates something worth stopping for. V4.1 Utility is designed for when restraint is the aesthetic choice, with flat lighting, front-facing composition, and simple, controlled scenes.

CRAISEE · Sep 4, 2026
ByteDance's flagship image editing model. Edit and compose with up to 10 reference images — product swaps, logo placement, multi-image fusion. Served via fal.ai.
CRAISEE · Sep 4, 2026
V4.1 is built on the same visual aesthetic and the same eye for what looks right, just pushed further across every dimension. The photorealism is more natural. The gradients are dreamier. Illustration styles are now possible that simply weren't before. And this is a model that reads a short prompts easier and creates something worth stopping for. V4.1 Pro generates higher-resolution images for when the idea deserves more room.
CRAISEE · Sep 4, 2026
V3 introduced major advances in photorealism and text rendering. It was the first Recraft model to generate mid-size text accurately and, as of 2025, is the only model capable of placing text at specific positions in an image.
CRAISEE · Sep 4, 2026
V4.1 is built on the same visual aesthetic and the same eye for what looks right, just pushed further across every dimension. The photorealism is more natural. The gradients are dreamier. Illustration styles are now possible that simply weren't before. And this is a model that reads a short prompts easier and creates something worth stopping for.
CRAISEE · Sep 4, 2026
MiniMax H3 Max is a next-generation general-purpose multimodal video model ranking #1 for overall quality, prompt understanding, and aesthetics in all evaluations, while generating a 5-second video in under 3 seconds.